What the answer leaves out.
A temple roof in Kyoto, a staffing plan in customer service, and why most of a decision has already happened before the AI answer arrives.
By Amit Srivastava · 18 October 2026
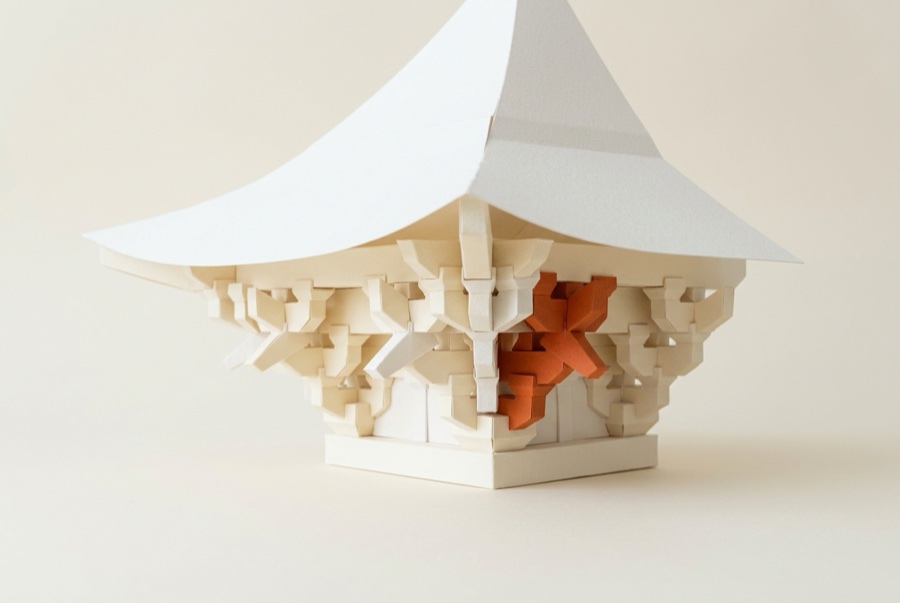
The photograph was clear in my mind before I typed a word.
Kiyomizu-dera in Kyoto, caught in late autumn light, maples turning red and gold beneath the great timber stage. I had stood there and taken the picture myself. When I asked an image-generation model in 2023 to recreate the scene, I thought my instructions were precise.
The image that came back was striking. The roof was wrong.
That small error turned into a useful education. The machine was building an image from patterns it had learned and the few words I had supplied. I was judging that image against a real structure, a memory and architectural joints I had never described. Between us lay an unspoken world.
We tend to stare at an AI’s answer. Most of the decision has already happened before the answer arrives.
The theory hidden inside a sensible request
Consider a composite customer-service manager called Ravi. His team is tired, queues are rising and the budget is under pressure. A vendor demonstration shows that a customer reply which used to take five minutes can now be drafted in ten seconds.
Ravi opens an AI assistant and types a practical request: Prepare a plan to reduce the size of the customer-service team.
Notice how much has been settled before the model generates a single line. As Herbert Simon argued decades ago, decision-makers never act on the whole world; they act on a simplified working picture of it. Daniel Kahneman later gave that habit a blunt name: what you see is all there is.
Ravi’s prompt contains message counts, salaries and typing speed. It leaves out the twenty minutes spent untangling a billing error across two departments, calming a customer whose parcel was lost twice, or spotting a product defect before it spreads. Those realities remain part of the business whether or not they fit inside the prompt.
Three blind spots in one room
The ABC Method names three questions that expose what a tidy working picture leaves out. All three operate together inside every consequential choice:
- A · Assumptions bridge the gaps in our evidence. Ravi sees faster reply drafting and assumes writing time accounts for whole jobs. Assumptions make action possible; danger starts when a guess quietly hardens into an unchecked fact.
- B · Biases tilt attention toward a favoured conclusion. Ravi spent six months arguing for the AI budget, so a forecast promising steep savings gets a warmer welcome than an operations lead’s awkward doubts.
- C · Complexity covers the relationships and knock-on effects our simplification cuts away. Automating easy tickets leaves human agents handling non-stop crises, while cutting experienced staff removes the very people able to notice when the machine is wrong.
Why human plus AI can count agreement twice
It is tempting to assume that pairing a manager with a capable model cancels out their blind spots. Often it multiplies them.
Ravi feeds his preferred framing into the chat box. The system returns a fluent, structured three-page case. Ravi reads his own premise reflected back in authoritative prose and treats that coherence as independent confirmation. Agreement has been counted twice.
Agreement is easy to count twice. Judgement needs a check outside the chat.
1,401
Participants studied: interacting with biased AI amplified human judgement bias (often without awareness), whereas accurate AI improved judgements.
106 studies
Human–AI teams beat humans alone on average, yet underperformed the stronger partner alone unless roles and checks were deliberately structured.
Where ABC intervenes in the meeting
- A
Assumptions
Write down what must hold true and check a sample of real operational cases before prompting.
- B
Biases
Build the strongest credible alternative and name one external fact that would change your mind.
- C
Complexity
Map downstream handoffs, edge cases and a named owner with time and authority to intervene.
Experimental research shows this risk is not merely theoretical. Across studies with 1,401 participants, Moshe Glickman and Tali Sharot found that interacting with a biased AI system amplified biases in human judgements (often without participants realising how much they had shifted), whereas accurate AI improved performance. Separately, a meta-analysis of 106 experiments by Michelle Vaccaro, Abdullah Almaatouq and Thomas Malone found that human–AI combinations beat humans alone on average, yet fell short of whichever partner performed better alone unless the division of work was carefully designed.
Asking the same model to critique itself can help, yet a second prompt is not a second source. What was missing from the room in turn one is still missing in turn two.
Run the same meeting differently
Now run Ravi’s meeting again with the same software and a different discipline, placing each check where it can still change the action:
- Assumptions before generation: Before asking for a staffing plan, the team writes down what must hold true for faster drafting to free whole roles, then checks a real sample of customer tickets against operational records.
2. Biases before agreement: Before backing a preferred plan, the team asks AI and frontline staff to build the strongest credible alternative, naming one piece of real-world evidence that would change their mind.
3. Complexity before commitment: Before signing off, the team maps downstream dependencies: repeat contacts, escalations, staff burnout and who holds both the time and authority to intervene when an automated reply misfires.
With the Kyoto photograph, I could spot the wrong roof in a second because I knew the temple. In management, the wrong roof looks like a persuasive board paper whose cost arrives nine months later as quiet customer churn.
Next time an AI answer lands on your screen looking complete, pause before forwarding it and ask one question:
What would we need to see in the real world (outside this chat window) for our answer to change?
Sources: Amit Srivastava, Why AI Isn’t Working at Work (September 2026, Ch. 5). Herbert A. Simon, Rational Decision-Making in Business Organizations (Nobel Lecture, 1978). Daniel Kahneman, Thinking, Fast and Slow (2011, WYSIATI). Moshe Glickman and Tali Sharot, “How human–AI feedback loops alter human perceptual, emotional and social judgements,” Nature Human Behaviour 9, 345–359 (2025; 1,401 participants). Michelle Vaccaro, Abdullah Almaatouq and Thomas W. Malone, “When combinations of humans and AI are useful,” Nature Human Behaviour 8, 2293–2303 (2024; 106 experiments from 2020–2023). Ravi is an illustrative composite.